Your machine downtime and your scrap, explained by the data you already have.
Jemba is the machine learning platform for production and continuous improvement teams. One CSV export is enough: in two weeks you know which machines are going to stop and which settings are losing material. After that, your teams run it themselves.
Your plant has been instrumented for a decade. The data died in storage.
Historians, PLCs, sensors and quality systems have been writing to disk for years. The tools that turn that into decisions take a year of integration and a data science team — so the export gets opened in Excel, and closed again.
The heavy artillery doesn’t reach down. Digital twins and first-principles models are excellent where they fit, and they do not amortise across a galaxy of smaller plants.
A pilot that needs a data scientist has already failed. If the analyst costs ten times the software, the software has no case.
Integration is where projects die. Not the maths — the six months of data plumbing before anyone sees a number.
A model is not an answer. A production team needs a setpoint range and a threshold, in the vocabulary of the line.
Two client lines. Two results blind-tested, not projections.
Each came from data the plant was already collecting — no new sensor, and no man-days asked of the client.
From the run/stop event log alone. No sensors, no process data.
977 columns of one existing export, screened down to 10 levers.
We run the first test on your data. After that, your teams run it.
For two weeks we prepare your export and test the model blind. If the result holds, Jemba passes into the hands of your process team: they pick the target variable, re-run the model in one click and read an operating range, not a notebook.
We publish the machines it didn’t work on.
On the aerospace line, two of four machines paid off and two did not. Both are in the deliverable, and neither of the two is priced into the case. The per-machine economics, the break-even per false alert and the validation method are all published in full.
Two algorithm families, three shop-floor questions.
Nothing below is a separate product. Each question is handled by one of the two families, and each one rests on a published client deployment.
“Does a serious stop start within the next hour?”
Read more →“Which variables really decide the yield?”
Read more →“Where should the line run so the yield holds?”
Read more →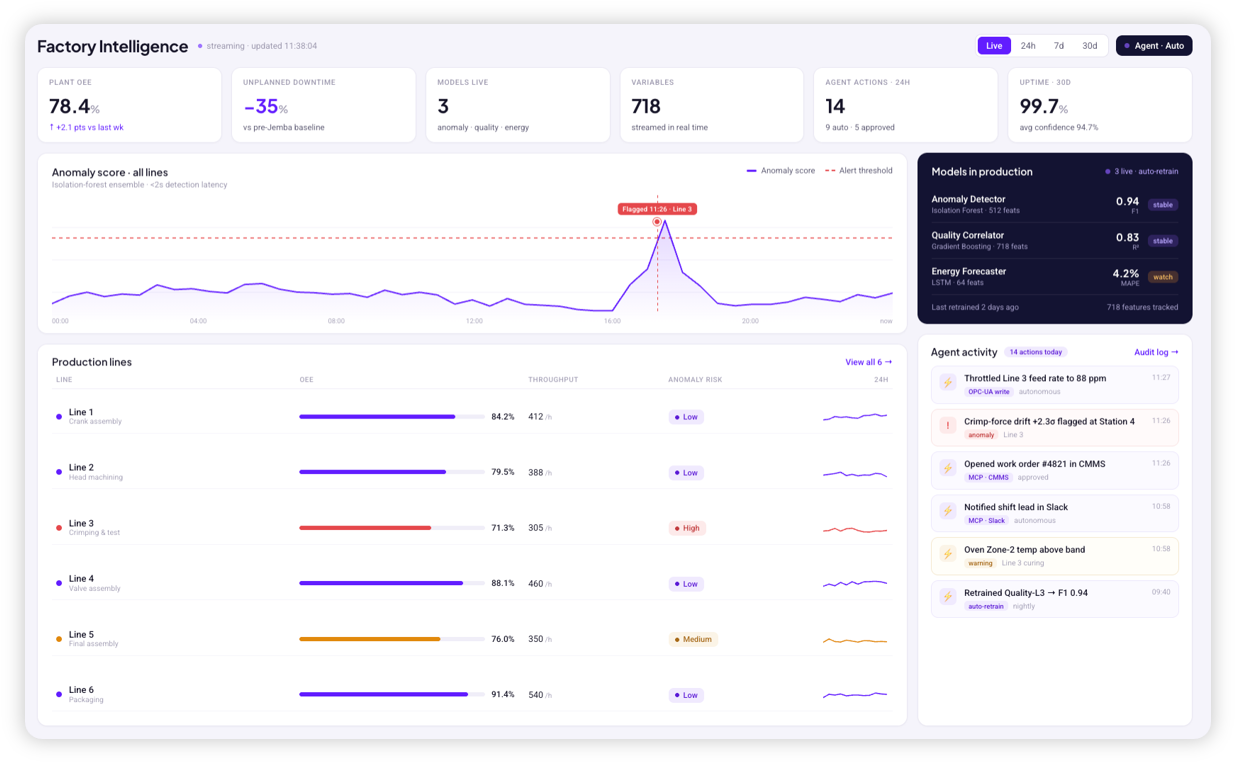
One line, one target variable, one export.
That is the whole ask. Two weeks later you have a validated case or a documented no — and either way you keep the finding.
Name one line and one target variable.
We read the export you already produce and tell you within a week whether it carries the levers — before you commit to anything.


